Project overview
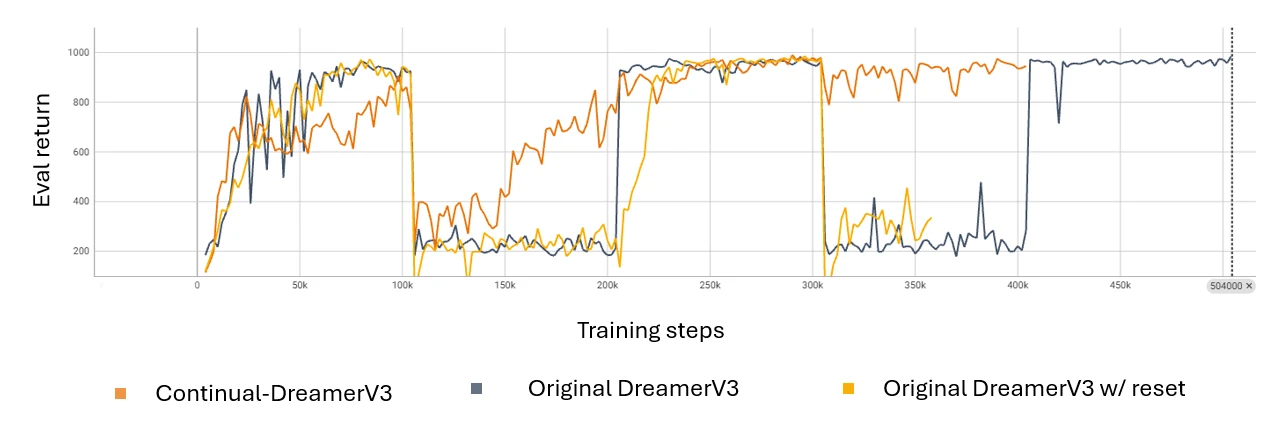
In this collaborative COMP 579 project with Zihan Wang and Thomas Lai, we adapted DreamerV3 for continual reinforcement learning by splitting its critic into transient and permanent value functions. The transient critic tracks current information while the permanent critic retains longer-term knowledge. We evaluated Continual-DreamerV3 on DeepMind Control Suite Walker Stand and Walker Walk tasks that alternated every 100,000 training steps, under the simplifying assumption that task boundaries were known. Across these experiments, the decoupled model retained prior behavior and adapted to task changes more reliably than the original DreamerV3 baseline. Additional experiments found that selectively reinitializing the value function at a task transition was particularly effective.